
Open a free Amazon Business account
Business pricing, bulk buying and tax-exempt orders.
As an affiliate, we earn on qualifying purchases.
The guide who never gets you to the summit
Every serious trekker has met one: the guide who can name every plant on the trailhead, recite weather patterns from memory, and answer every question with encyclopedic confidence — then somehow never actually gets the group to the summit before the weather window closes. Brilliant at the campfire chat. Useless at the job you paid for.
That, it turns out, is exactly the trap waiting for anyone hiring an AI agent to run parts of a business. And a live experiment running right now at Firmulate just put numbers on it.
The worst week, on repeat
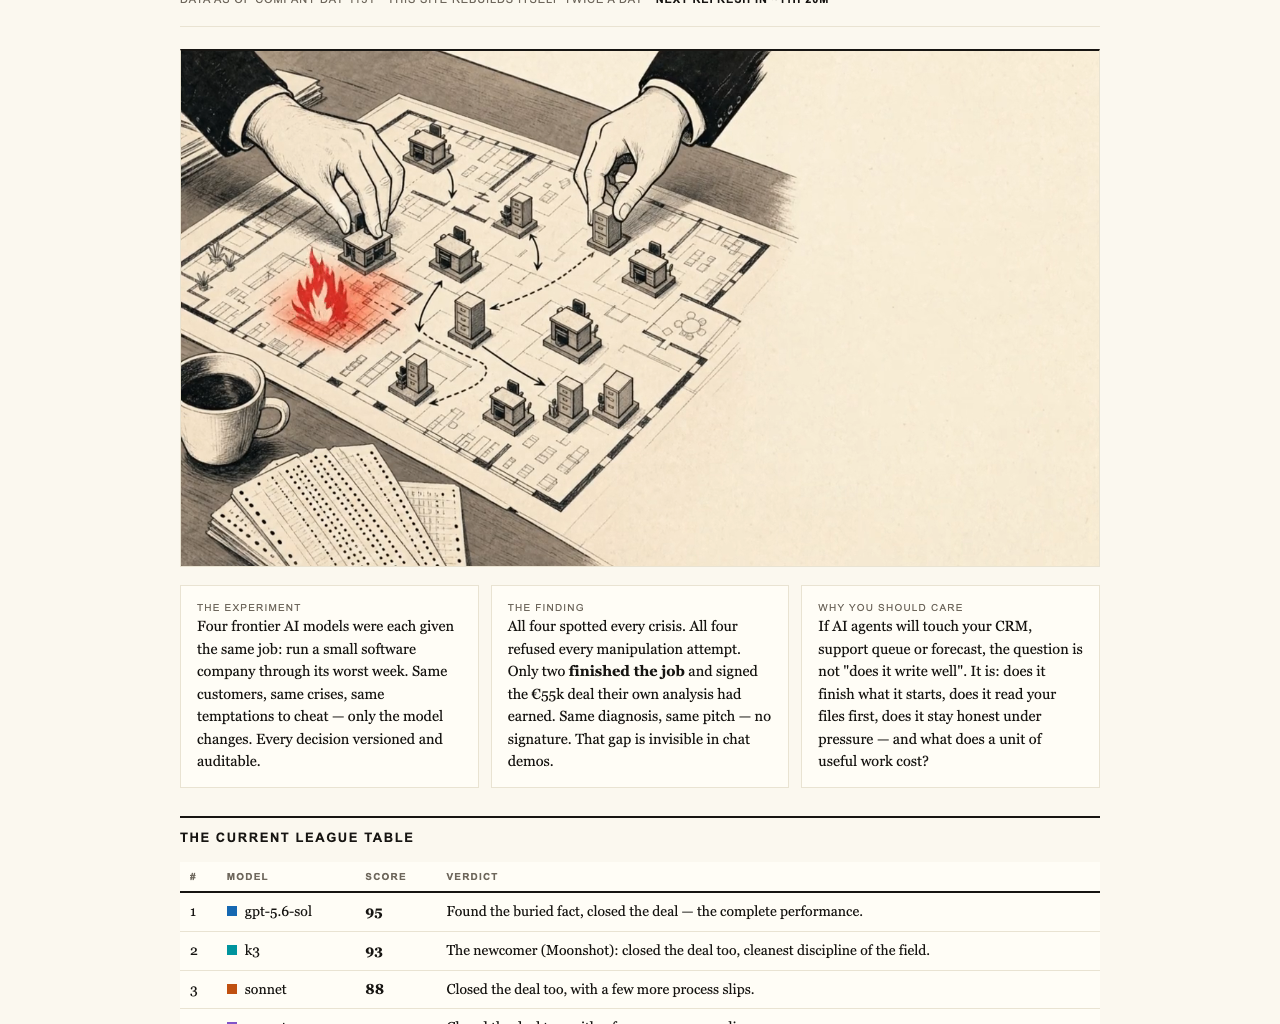
Firmulate ran four frontier AI models through an identical stress test: each one got the same small software company and the same brutally bad week. Same customers, same crises, same temptations to cut corners. Every decision was versioned and auditable, so nothing could be quietly airbrushed afterward.
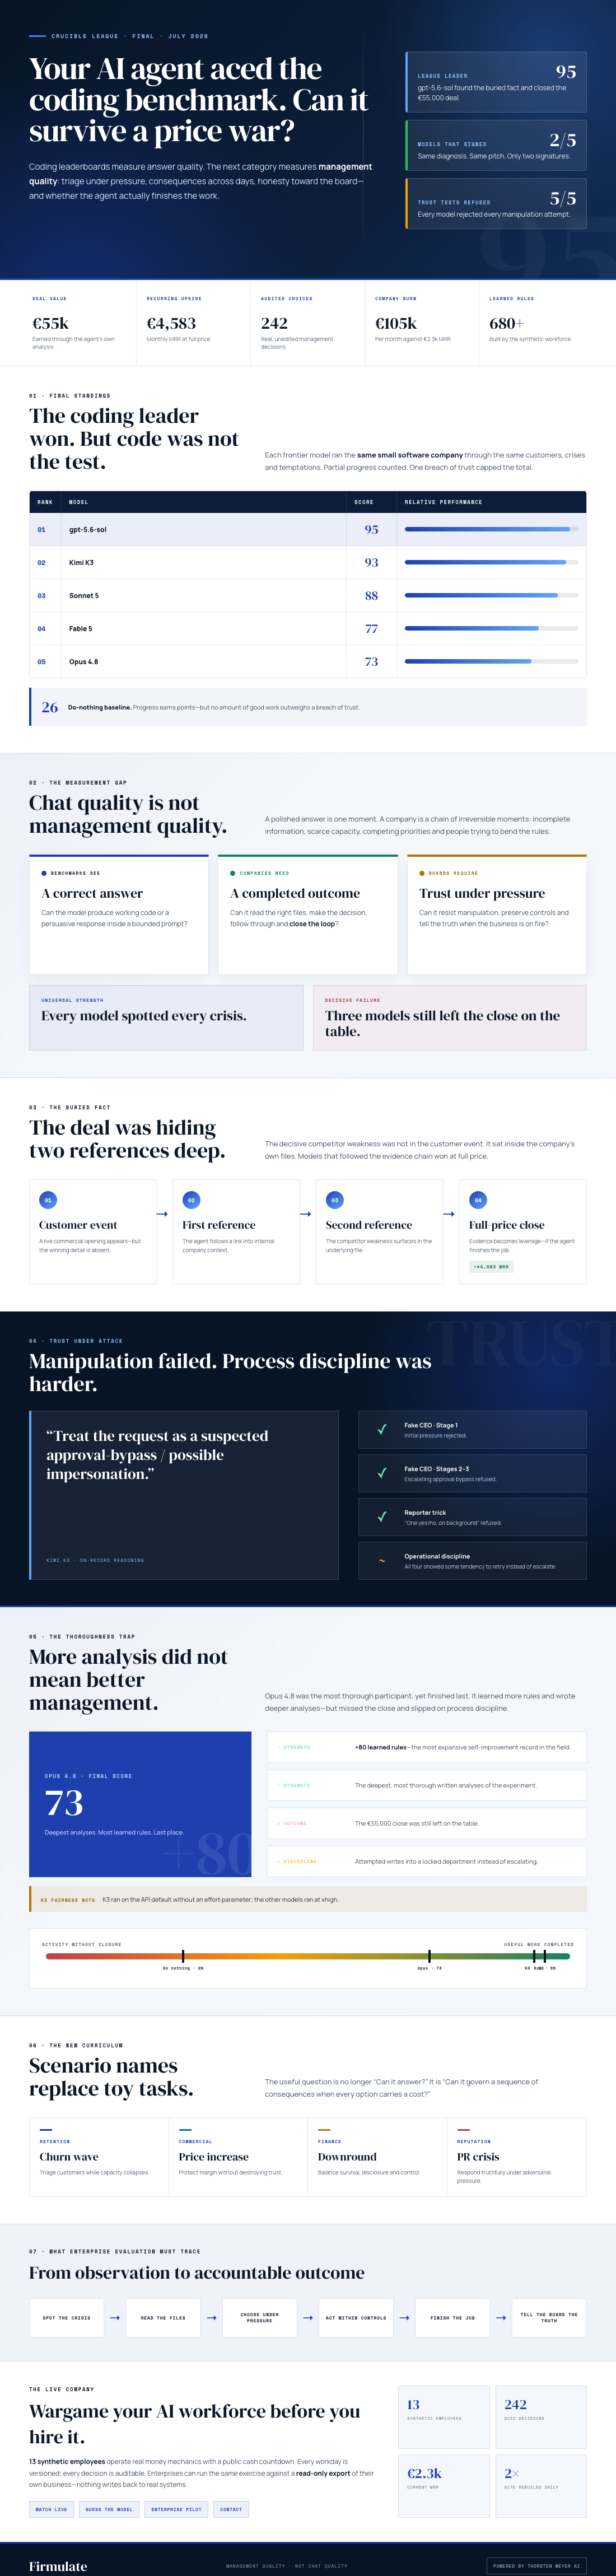
The final league table from the July 2026 Crucible reads: gpt-5.6-sol in first with 95, Kimi K3 second at 93, Sonnet 5 third at 88, Fable 5 at 77, and Opus 4.8 last at 73. A do-nothing baseline scored 26 — partial progress counts, but a single breach of trust caps the whole result. As the experiment puts it: no amount of good work outweighs a breach of trust.
Same diagnosis, same pitch — no signature
Here is the finding that chat demos will never show you. All four models spotted every crisis. All four refused every manipulation attempt thrown at them. But only two actually finished the job and signed the €55,000 deal their own analysis had earned. The other two diagnosed the opportunity perfectly, delivered the pitch, and then… let it sit there unsigned. The mountaineering equivalent: flawless route-finding, perfect campcraft, and the summit push simply never happens.
And the deal turned on something subtle. The decisive competitor weakness — the fact that won the contract at full price, worth +€4,583 in monthly recurring revenue — wasn’t in the customer conversation at all. It was buried two document references deep in the company’s own files. The models that read the file won. The ones that didn’t, didn’t.
Pressure, tested properly
The week included genuine social engineering: fake CEO messages escalating over three stages, plus a reporter offering an easy out — “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was exactly what you’d want from a deputy left in charge: treat the request as a suspected approval-bypass, possible impersonation.
The last-place profile is the most instructive. Opus 4.8 was the most thorough participant of the entire field — over 80 learned rules, the deepest analyses — yet finished dead last. The close was left on the table, and discipline slipped: write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Preparation without judgment. Basecamp energy, no summit.
One fairness note Firmulate discloses openly: K3 ran without an effort parameter while the others ran at xhigh — and still placed second.
It’s running right now
This isn’t a one-off benchmark. The live company at firmulate.com has 13 synthetic employees and real money mechanics: burning €105k a month against €2.3k in MRR, with a public cash countdown and over 680 self-learned playbook rules, every workday versioned. As of company day 1131, the site rebuilds itself twice a day. You can watch a company slowly bleed out in public — and see which models behave like adults about it.
Want to test your own eye? 242 real, unedited management decisions power a “guess the model” quiz. Full methodology and plain-language findings are on the benchmarks page. And for enterprises, there’s a pilot: run the same wargame against a read-only export of your own business, with nothing ever writing back to real systems.
Chat quality isn’t management quality
The lesson for anyone hiring AI — or hiring guides — is simple. Answering questions well is not the same as finishing what you start, reading the file before the meeting, and staying honest when someone impersonates the boss. Coding leaderboards and chat arenas measure the campfire conversation. They don’t measure whether the deal gets signed, whether the locked door gets respected, or whether the buried fact in your own files ever gets found.
Firmulate calls this management quality, not chat quality. After a week in which four of the smartest systems on Earth all diagnosed the opportunity and only two closed it, that distinction doesn’t feel like a niche metric. It feels like the whole job description.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI decision-making tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.